Reusing DD names in sequenced translators

We need to run a pre-process step prior to a compile. The pre-process step uses similar DD cards to the compile step. The output of the pre-process step (e.g. SYSUT2) should go into the SYSIN of the compile step (which happens to also need a DD Card named SYSUT2). Therefore, I specified the SYSUT2 in the pre-process step as keep.
We found this in the documentation https://www-01.ibm.com/support/knowledgecenter/SSYMRC_4.0.6/com.ibm.team.concert.doc/topics/r_rtcz_same_name_for_temp_data_set_with_keep_in_translator.html?lang=en. Does this mean that I have to specify a different name for SYSUT2 in the DD Names list? Would this work in other cases where we use our own DD Card names (as opposed to one of the "IBM" supported DD names that can be used in the DD Names List)?
If I don't do something in the DD Names list, I get an error File in Use when the second SYSUT2 allocation is attempted during the compile step. This could be a major problem for us if we have to be very explicit about how we specify and sequence these steps so that they can use the needed DD cards.
BTW, we also have a similar problem with SYSXMLSD, both steps should be able to write error feedback into that file.
2 answers
Hi Alex,
the DD Names List utilizes the DD Name substitution facility that the IBM compilers, assembler and DFSMS utilities use. You can find information relating to this in all of the programming guides and utility reference. But for ease of reference I provided this in an SCLM redbook in Appendix E - DDname substitution lists. So to answer your 2nd question, "would this work in other cases where we use our own DD Card names" the answer would be no. However there is an option that may work for that, I will come to that in a moment. So to answer your first question, "Does this mean that I have to specify a different name for SYSUT2 in the DD Names list?" the answer is yes. A good example is IEBGENER. I uses SYSUT1 and SYSUT2 for input and output. If the output from SYSUT2 needs to go into the COBOL compiler then there will be an issue, as COBOL also uses SYSUT2, but for a work data set. So to get this to work the IEBGENER step needs to use the DDname list, and specify Keep on the temporary data set.
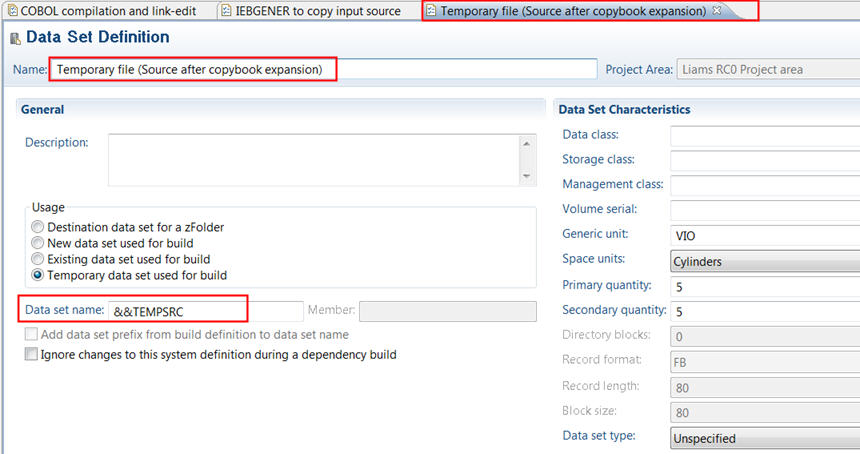
The data set definition for the temporary data set defines a data set name of &&TEMPSRC.
Then language definition in the example I will use has a 1st translator of IEBGENER that will copy the actual source into a temporary data set. The 2nd translator is the COBOL compile that will take the temporary data set as input.
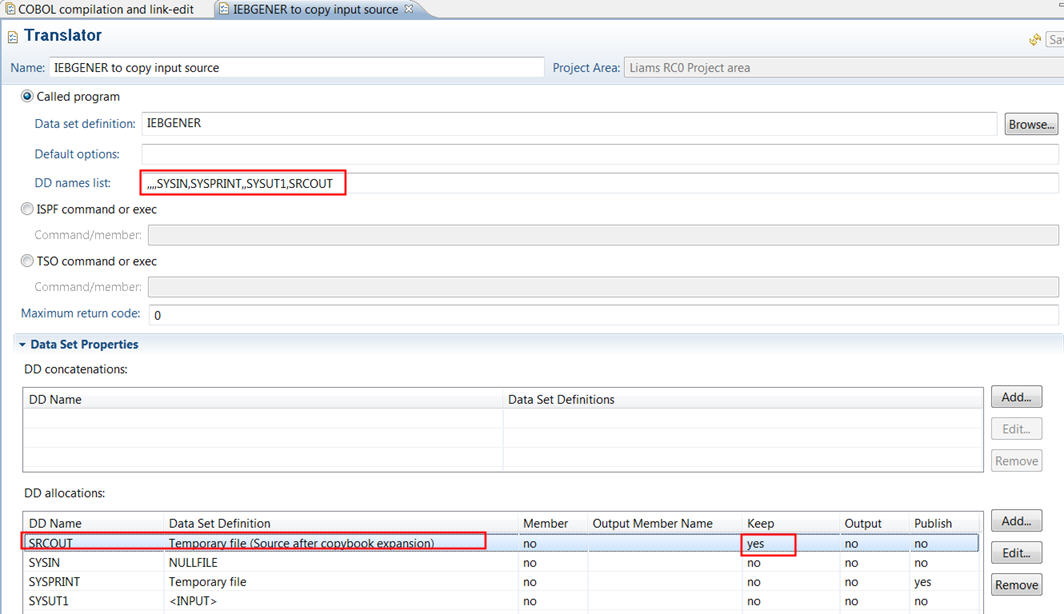
For the IEBGENER translator the DDnames list has ,,,,SYSIN,SYSPRINT,,SYSUT1,SRCOUT so we are replacing SYSUT2 with SRCOUT. Note the 4 "," at the beginning as the ddname substitution is positional. Then in the DD allocations we allocate DD SRCOUT instead of SYSUT2, and use the data set definition that defines &&TEMPSRC using the KEEP option.
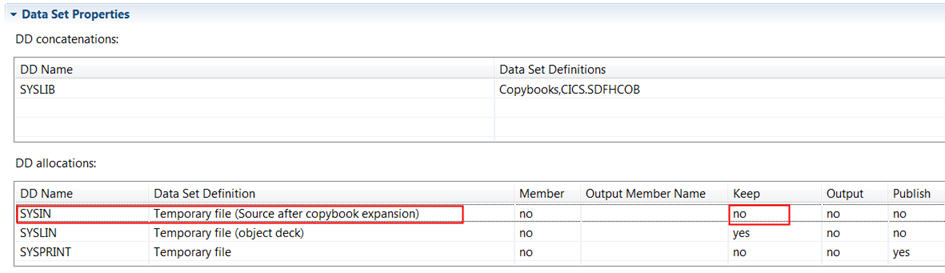
Finally in the COBOL compile translator we use the definition that defines &&TEMPSRC and associate that with the SYSIN DD. This will allow the compile to work as SYSUT2 can be allocated normally by the COBOL compile step.
We can use IEBGENER steps in a number of translators including your own home written ones. If there is a conflict in DD names between 2 translators you can always put an IEBGENER in between them to rename the data set names as IEBGENER supports the DD names list.
the DD Names List utilizes the DD Name substitution facility that the IBM compilers, assembler and DFSMS utilities use. You can find information relating to this in all of the programming guides and utility reference. But for ease of reference I provided this in an SCLM redbook in Appendix E - DDname substitution lists. So to answer your 2nd question, "would this work in other cases where we use our own DD Card names" the answer would be no. However there is an option that may work for that, I will come to that in a moment. So to answer your first question, "Does this mean that I have to specify a different name for SYSUT2 in the DD Names list?" the answer is yes. A good example is IEBGENER. I uses SYSUT1 and SYSUT2 for input and output. If the output from SYSUT2 needs to go into the COBOL compiler then there will be an issue, as COBOL also uses SYSUT2, but for a work data set. So to get this to work the IEBGENER step needs to use the DDname list, and specify Keep on the temporary data set.
The data set definition for the temporary data set defines a data set name of &&TEMPSRC.
Then language definition in the example I will use has a 1st translator of IEBGENER that will copy the actual source into a temporary data set. The 2nd translator is the COBOL compile that will take the temporary data set as input.
For the IEBGENER translator the DDnames list has ,,,,SYSIN,SYSPRINT,,SYSUT1,SRCOUT so we are replacing SYSUT2 with SRCOUT. Note the 4 "," at the beginning as the ddname substitution is positional. Then in the DD allocations we allocate DD SRCOUT instead of SYSUT2, and use the data set definition that defines &&TEMPSRC using the KEEP option.
Finally in the COBOL compile translator we use the definition that defines &&TEMPSRC and associate that with the SYSIN DD. This will allow the compile to work as SYSUT2 can be allocated normally by the COBOL compile step.
We can use IEBGENER steps in a number of translators including your own home written ones. If there is a conflict in DD names between 2 translators you can always put an IEBGENER in between them to rename the data set names as IEBGENER supports the DD names list.
Comments
For the first, it should be able to. I would need to set it up to test, I will have to wait till I am back in Australia. But it looks like you are reworking your first step to not use SYSUT2.
For the 2nd, looks like you found what you needed.
For the 3rd, not a limitation that I am aware of. I just checked my COBOL/CICS/DB2 co-processor translator and I have a mixture:
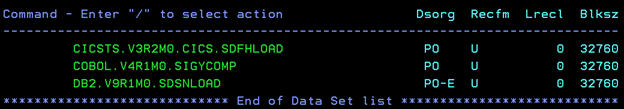
Were all your blocksizes the same? Not sure that would make a difference. Did all the libraries in TASKLIB need to be APF authed, and the one you added was not? I would expect to see a S047 abend in the system log if that was the case.
For the 2nd, looks like you found what you needed.
For the 3rd, not a limitation that I am aware of. I just checked my COBOL/CICS/DB2 co-processor translator and I have a mixture:
Were all your blocksizes the same? Not sure that would make a difference. Did all the libraries in TASKLIB need to be APF authed, and the one you added was not? I would expect to see a S047 abend in the system log if that was the case.